On October 22, 2026, another sharp traffic spike appeared in ICanUp Admin Analytics.
At that point there were 527 total views. 474 were attributed to Germany, 481 to mobile devices, and 506 to Chrome. Posts had 400 views but only 65 deduplicated views.
Around 07:00 Kyiv time, the graph rose sharply.
From the dashboard alone, this could look like a wave of normal mobile readers. But after similar incidents on October 8-9, I no longer wanted to draw conclusions from a User-Agent or one analytics metric.
Analytics Gave Me a Signal, Not an Answer
Two things stood out: traffic was highly concentrated in one device/browser profile, and there was a large gap between raw post views and deduplicated views.
That gap alone does not prove automation. I discuss it separately in the article about the gap between total views and deduplicated views. Here it was simply the reason to move from the dashboard to server logs.
Before Reading Logs, I Aligned the Time Zones
Admin AnalyticsEurope/Kyiv Nginx access logsUTC Investigation windowconvert first, filter secondThis is a small step, but skipping it makes it easy to investigate the wrong minute.
Analytics used Europe/Kyiv reporting time while Nginx access logs used UTC. I converted the investigation window first and only then started aggregating requests.
There Were 1600 HTTP Requests in Three Hours, but the Main Spike Was Much Shorter
Between 06:00 and 09:00 Kyiv time, Nginx recorded 1600 HTTP requests across several virtual hosts on the server.
The sharpest moment was at 07:44: 623 requests in one minute.
The main client made 740 requests in roughly three minutes, including 621 in a single minute, and touched 129 different URLs.
The User-Agent Looked Normal. The Behavior Did Not.
Client profile Android 10Chrome 131Mobile Observed behavior 740 requests / ~3 min621 requests / 1 min129 distinct URLs40-51 requests to some new articlesThe main User-Agent looked like a normal Android Chrome Mobile browser.
But some newly published articles were requested 40-51 times within a very short interval. The request pattern was a much stronger signal than the browser string.
This continues the lesson from the previous article about traffic that looks human but behaves like a bot: a User-Agent describes what the client claims to be; it does not prove that a human is behind it.
The HTTP Status Distribution Explained More Than the Request Count Alone
Main client 499 441301 224200 33403 32404 10 Total 740441 responses had status 499. In Nginx, that means the client closed the connection before the server finished the response.
So 740 HTTP requests cannot be translated into "740 pages were successfully read." And 740 requests do not mean 740 Laravel Analytics views either.
Only 33 responses for this client ended with 200. Much of the rest consisted of redirects, client-aborted requests, forbidden responses, or not-found responses.
I Separated HTTP Requests, Laravel Page Views, and Deduplicated Views
Nginx request | vmay stop at redirect / 403 / 404 / 499 Laravel request | vmay or may not create analytics view Analytics view | vmay or may not create a new deduplicated viewThis also matters for the later Human/Bot analytics investigation.
An automated client using a mobile Chrome User-Agent may pass a User-Agent-based detector as a normal browser. But from aggregated data alone, I cannot honestly claim that all 740 requests were recorded as Human Analytics.
That requires a separate verification: which classifier version was deployed, which requests actually reached Laravel, and which of those created view events.
One Time Window Contained Several Independent Traffic Sources
After grouping requests, it became clear that not all suspicious traffic belonged to one client.
- Main high-volume client: 740 requests to 129 URLs.
- Separate scanner: 227 requests to 224 URLs, with 222 ending in 404.
- Separate crawler claiming a Sogou User-Agent: 163 requests to 160 URLs.
- Other clients: isolated probes for older PHP, PHPUnit, and CGI weaknesses.
I do not merge them into "one attack" because the logs do not prove that. Sharing a time window does not mean sharing an operator.
One of My First 503 Hypotheses Was Wrong
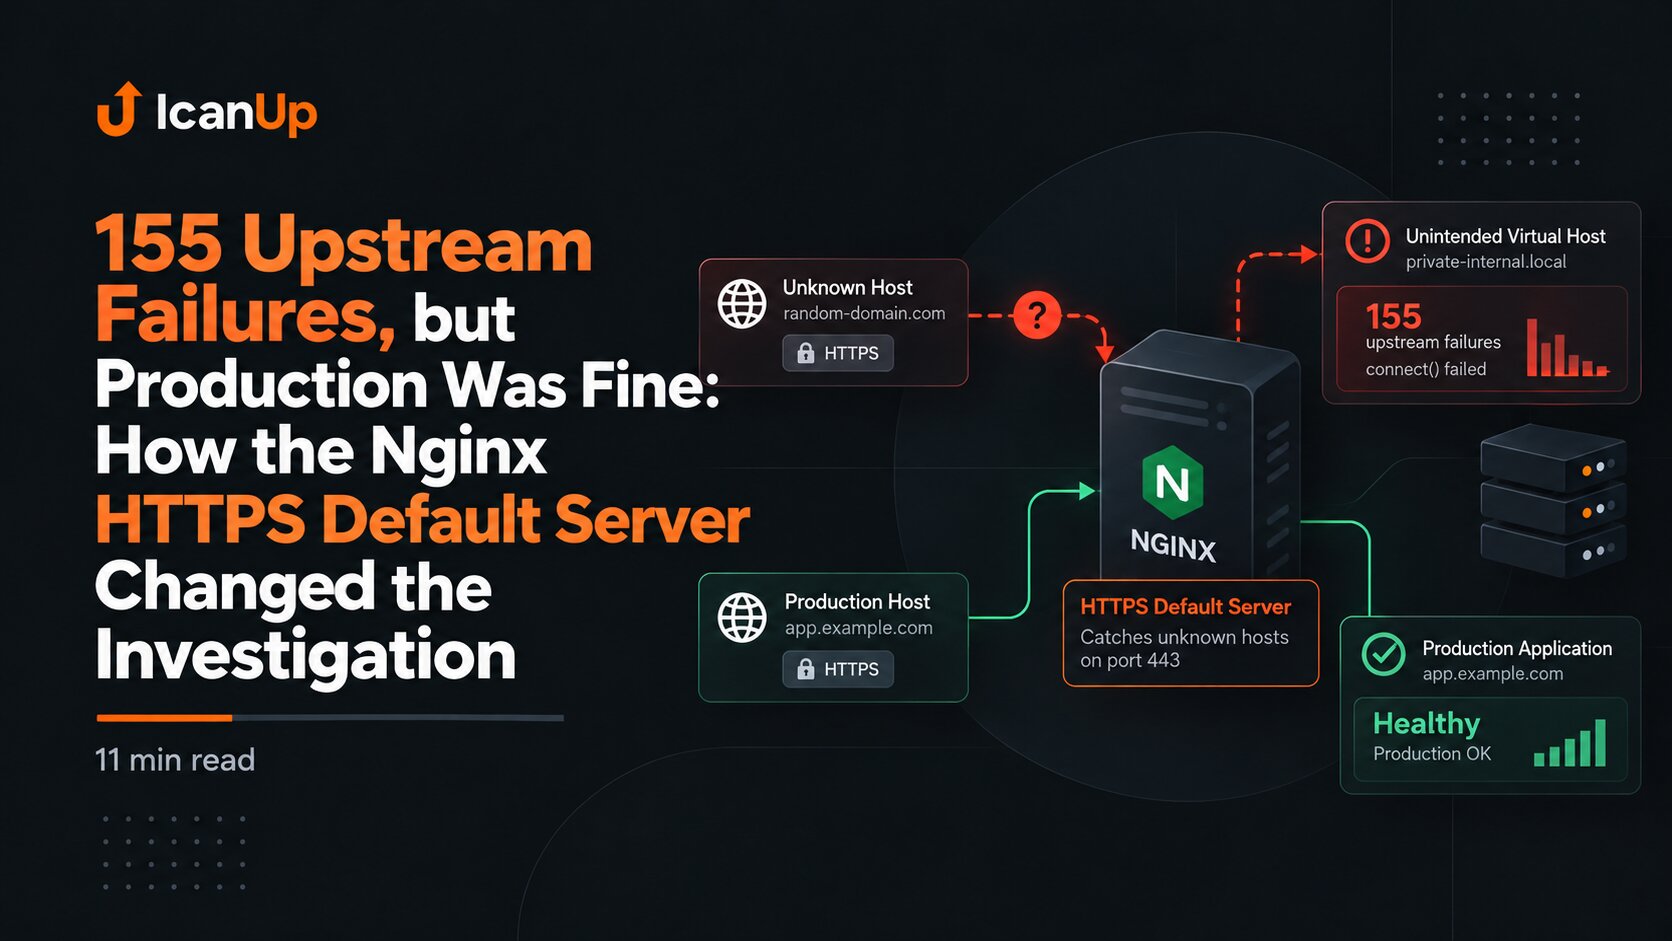
In the same investigation window, I saw 155 upstream connection-refused errors and initially suspected that the high-volume traffic might have affected availability of the main production application.
The error log did not support that hypothesis. All 155 errors belonged to another virtual host with a separate backend, while the main production site kept responding.
I separated that story into another article because it is a different topic: HTTPS default-server behavior, virtual-host routing, and why a shared Nginx error log must be read in context.
Fail2ban Was Already Working, but It Solved a Different Problem
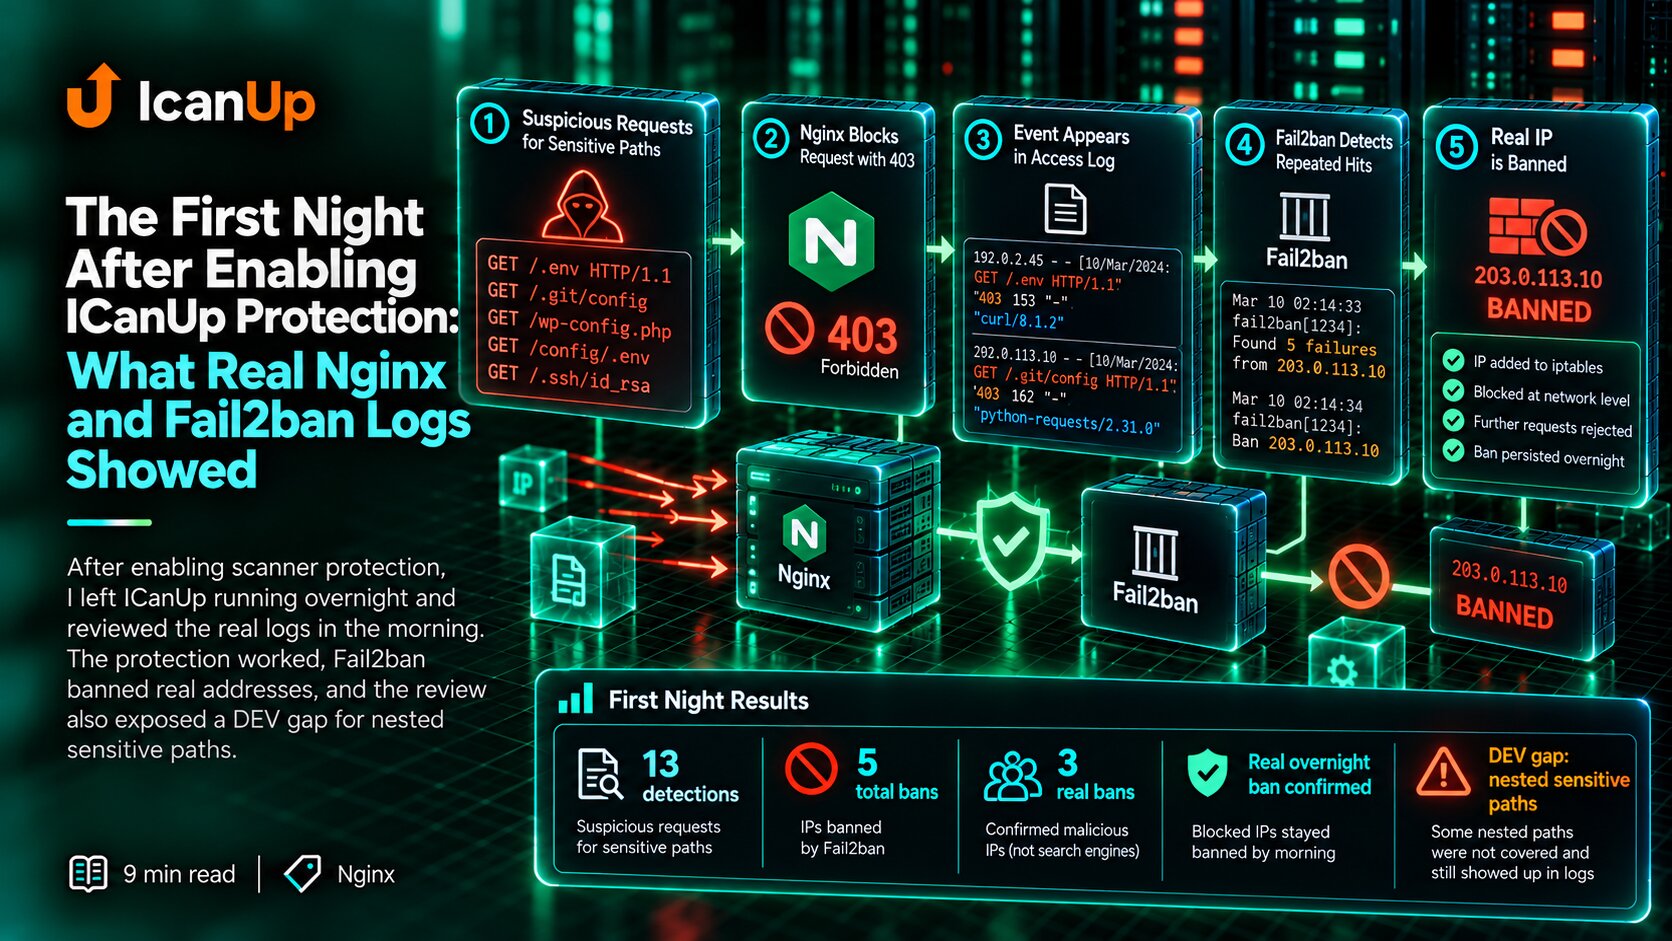
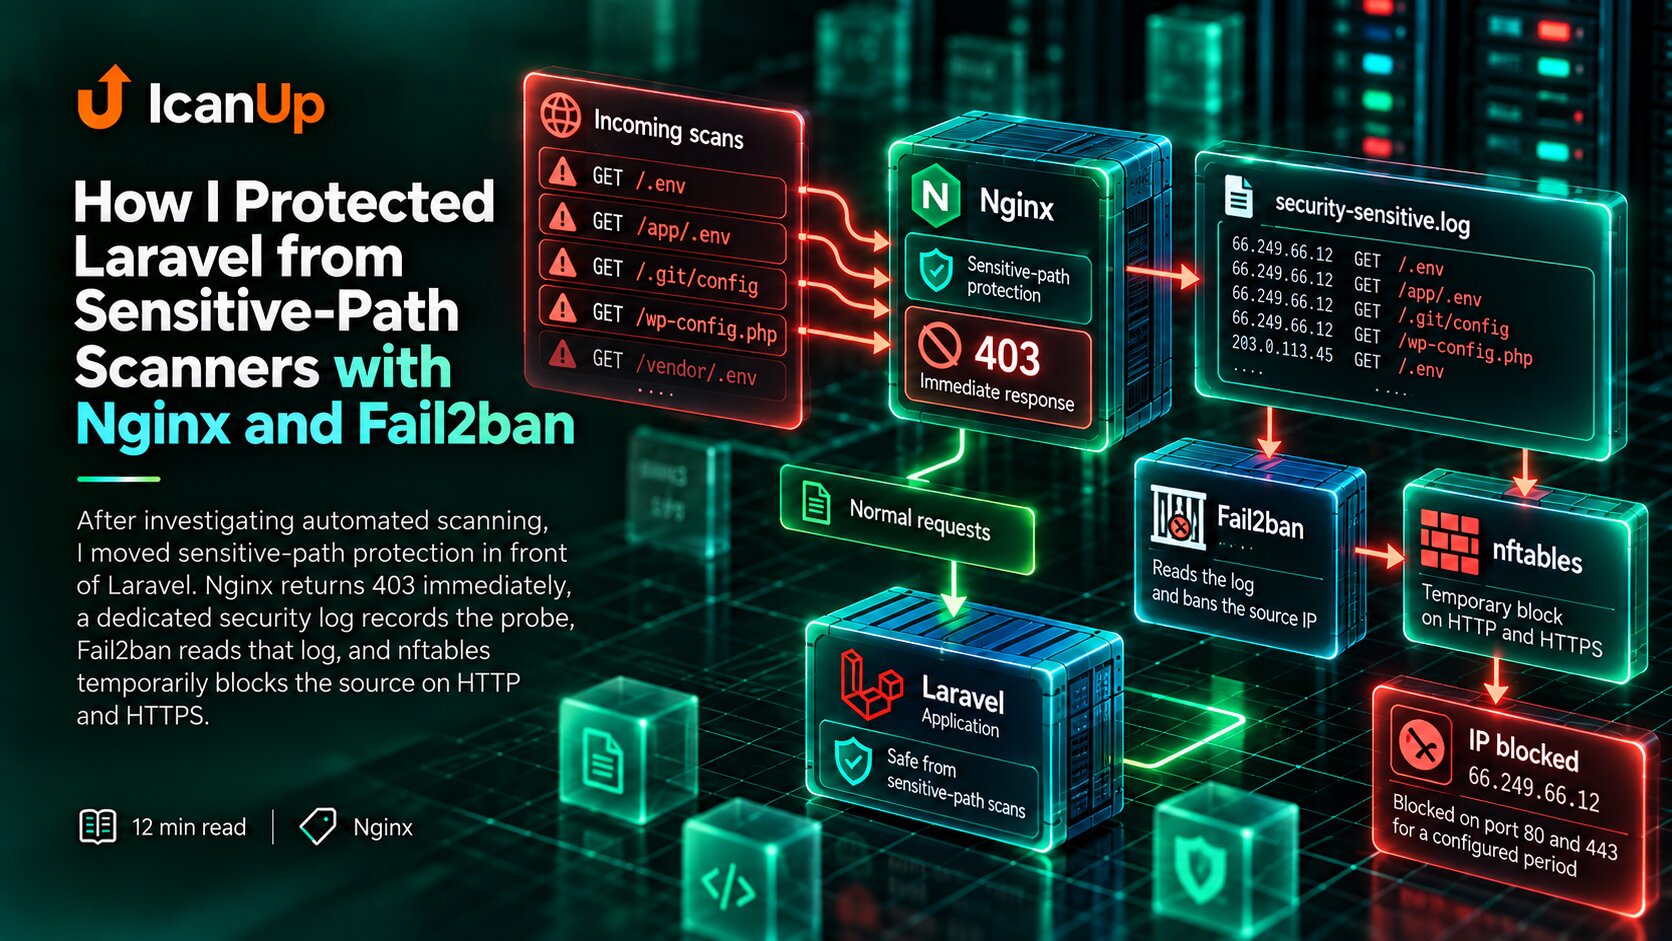
Before this incident, the server already had an Nginx layer for suspicious sensitive-path requests plus Fail2ban rules that blocked confirmed scanners through the firewall.
By the end of the investigation, Fail2ban reported 41 filter events, 9 bans in total, and 5 active bans. The main high-volume client address was also already present in the ban list.
So the conclusion "Fail2ban is not working" would have been wrong. It was enforcing the rules it was designed to enforce.
Sensitive-Path Protection and Rate Limiting Target Different Patterns
Sensitive-path scanner /.hidden-config/old-admin-probe/archive-probe => path-based rejection=> security log=> Fail2ban candidate High-volume normal-path client /posts/article-a/posts/article-b/posts/article-cThis is where the protection gap became clear.
Path-based rules work well when a scanner requests obviously suspicious resources. But a client can make hundreds of requests to completely valid /posts/... routes without violating any sensitive-path rule.
I describe the sensitive-path model separately in the separate article about Nginx and Fail2ban for sensitive-path scanners. The new incident showed that this layer is not enough for high-volume behavior on normal URLs.
I Did Not Block a Country, Chrome Version, or All Mobile Traffic
About 90% of views coming from Germany looked unusual. Android 10 / Chrome 131 repeated. One IP address generated a very large number of requests.
But none of those signals alone is strong enough to become a bot-classification rule.
Geolocation may represent a VPN, hosting provider, proxy, or a real reader. A User-Agent is easy to spoof. A shared IP may represent multiple users.
So I wanted enforcement to respond to behavior rather than one weak attribute.
The Next Layer Was Nginx Rate Limiting
I added a dedicated limit_req_zone for production dynamic requests and attached it to the PHP handler.
I intentionally do not publish exact production thresholds here: they depend on traffic baseline, burst behavior, infrastructure capacity, and whether a shared proxy sits in front of the server.
For this article, the important part is the shape of the configuration.
limit_req_zone $binary_remote_addr zone=app_dynamic:10m rate=<tested-rate>; location ~ \.php$ { limit_req zone=app_dynamic burst=<tested-burst> nodelay; limit_req_dry_run on; limit_req_status 429; limit_req_log_level warn; # existing PHP handling}The Key Decision Was Dry-Run Before Enforcement
I did not want to fix automated traffic at the cost of false positives for real readers.
An IP-based rate limit has an obvious risk: several legitimate users may share one NAT, corporate gateway, or mobile carrier. An SPA, assets, or parallel requests may also produce short bursts.
So the first mode was limit_req_dry_run on. Nginx can observe and log threshold violations without rejecting the request.
After the Change, I Checked More Than nginx -t
Nginx config validation PASSReload PASS Production 200Development 401Private service 401Unknown HTTPS hostname rejected Dry-run over-limit eventsat verification time 0The configuration passed validation and reload, and expected access behavior across the relevant virtual hosts remained correct.
At verification time, dry-run had not recorded new over-limit events. This negative result matters: I cannot claim that the new rate limit already stopped the previous client.
The limit was introduced after the incident, and another comparable spike had not yet occurred during the verification window.
I Treated Production Hardening as a Reversible Change
Before editing Nginx configuration, I saved a backup. After the change I ran validation, then reload, and only then verified HTTP behavior.
When a warning appeared because HTTPS listen parameters were inconsistent, I did not leave it for later. I aligned the configuration and ran nginx -t again.
Security hardening should not create new production uncertainty.
I Deliberately Left Some Questions Open
After the incident investigation, I still did not have enough evidence to answer several questions honestly.
- Which exact bot-classifier version was deployed in production during the spike?
- Which high-volume HTTP requests actually reached Laravel?
- Which of those produced analytics view events?
- Can the existing aggregates prove an impact specifically on Human metrics?
That is why I did not automatically delete or reclassify historical analytics.
What This Incident Changed in My Protection Model
- A normal browser User-Agent does not prove human behavior.
- HTTP requests, Laravel views, and deduplicated views are different observation layers.
- HTTP 499 must not be treated as a successfully read page.
- Shared Nginx logs must be read in virtual-host context.
- Sensitive-path protection and volume-based limiting solve different problems.
- Country, Chrome version, or one IP address should not become a bot rule by itself.
- New enforcement is safer when observed in dry-run first.
- Unproven results should remain explicitly unproven.
The Protection Improved Through Better Boundaries Between Signals
The most useful result of this incident was not one specific rate limit.
I made the boundaries clearer between analytics signals, Nginx request evidence, path-based scanner protection, firewall bans, and volume-based control.
740 requests in three minutes showed that a working Fail2ban setup does not mean complete protection from every kind of automation. The next layer had to be added separately, and before real blocking, its effect on legitimate users had to be observed first.
Production security became stronger when I stopped looking for one universal rule and started separating different kinds of abnormal behavior.