Many systems keep data that is not the primary truth but is needed for fast reads.
Examples include counters, denormalized totals, projections, search indexes, cached aggregates, or read-model tables.
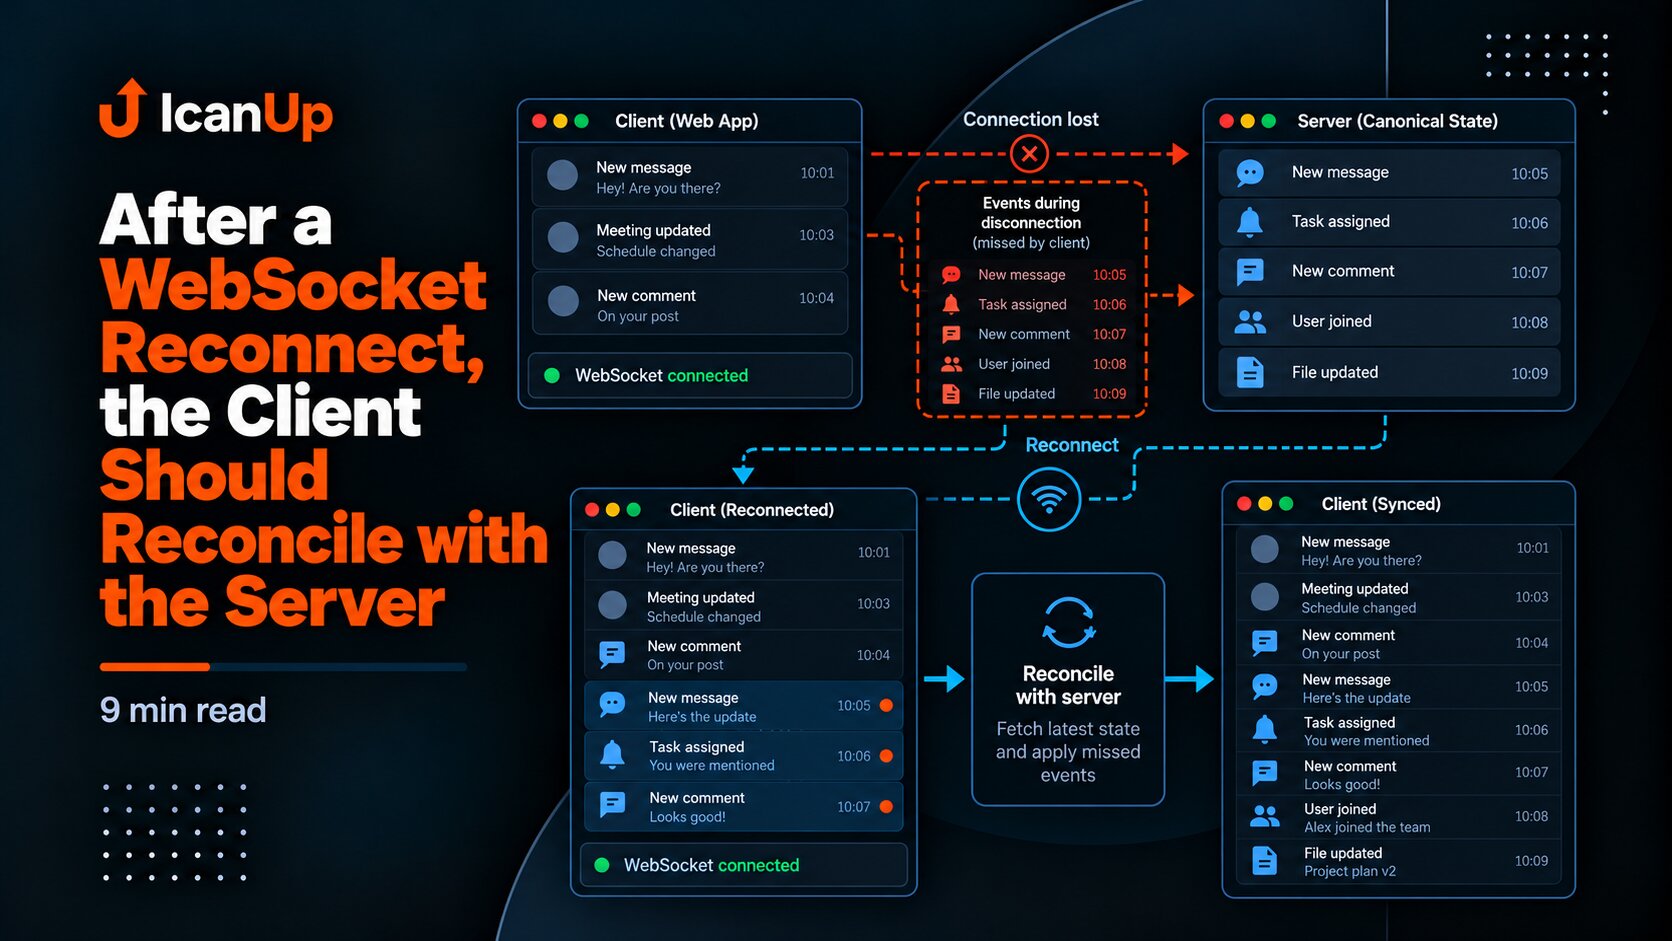
While everything works correctly, those structures are almost invisible. After a missed event, queue failure, bug, or bad deployment, derived state can drift away from canonical data.
If the system has no standard way to verify and repair that drift, the repair command is usually written during the incident under pressure and with weaker guarantees.
Start by Separating Canonical and Derived Data
Repair is only possible when it is clear what the state should be rebuilt from.
For example, an unread-message count may be derived from messages and read records. A search index may be derived from primary entities. A daily aggregate may be derived from individual operations.
If a derived field starts carrying unique information that exists nowhere else, it is no longer safely rebuildable.
A Useful Repair Path Has Four Explicit Stages
canonical data -> recalculate expected state -> compare with stored state -> repair if neededIt is important not to jump directly to writing a new value.
The system should first be able to calculate the expected state without changing anything, compare it with what is stored, and only then perform a controlled repair.
The same logic can then support diagnostics, monitoring, manual checks, and the repair itself.
Recalculation Should Be a Separate Operation
final class RecalculateUnreadCount{ public function handle( User $user, ): int { return Message::query() ->forUser($user) ->unread() ->count(); }}Such a service can be called from a command, test, administrative check, or background job.
If recalculation immediately mutates data, it becomes harder to understand the size of the drift before repair.
Comparison Before Writing Gives You a Safe Verification Mode
user_id=42stored=18expected=21difference=+3status=DRIFTA check-only mode is especially useful for large datasets.
It lets you answer first: how many records are wrong, how large the difference is, and whether the issue is local or systemic.
That is much safer than running a command that immediately rewrites thousands of rows.
A Repair Command Should Have an Explicit Write Mode
php artisan app:repair-unread-counts # check only php artisan app:repair-unread-counts --write # apply repairA normal invocation without options can be diagnostic only.
Actual writes require an explicit flag. This reduces the risk of accidentally performing a mass repair while investigating an issue.
Repair Should Be Idempotent
If the command has already restored the correct state, running it again should not create new changes.
For derived values this is a natural property: each run calculates the expected result from canonical data and aligns the stored value with it.
Repair Should Support a Limited Scope
A full-system rebuild is not always necessary.
It is useful to scope verification to one user, one aggregate, a time range, one entity, or a small set of identifiers.
This speeds up diagnosis and reduces risk during targeted repair.
Mass Repair Should Not Become One Long Transaction
For a large table, it is better to process records in batches, persist progress, and avoid holding locks longer than necessary.
In some cases, canonical state should be read again immediately before writing so that changes made during a long recalculation are not overwritten.
A Search Index Follows the Same Principle at a Larger Scale
A search index is often fully rebuildable from the primary database.
Alongside incremental updates, it is useful to keep a standard full rebuild path: generate expected documents, detect missing or extra records, and reindex when needed.
If the system only knows how to update the index after a model change but cannot rebuild it, it depends much more heavily on never missing an event.
A Projection Without a Rebuild Path Becomes a Hidden Risk
Projections are useful because they optimize reads. That optimization should not make the data unrecoverable.
If a projection is built from events or primary tables, its builder should be reusable both during normal processing and during a full rebuild.
A Repair Command Should Not Hide a Recurring Bug
Having a standard repair path does not mean drift can be ignored.
If the command repeatedly finds the same kind of drift, the underlying cause should be fixed: a missed event, incorrect listener, стан гонитви, incomplete transaction, or wrong update model.
The repair path is a safety mechanism and recovery tool, not a routine replacement for correct business logic.
Repair Checks Can Also Become an Observability Signal
When comparison is separated from writing, it can be run periodically for samples or critical aggregates.
This allows the system to detect drift before a user notices it.
The frequency and scope should still match the cost of the check and the importance of the data.
What to Test
1. Correct derived state produces no repair.2. Drift is detected without writing in check-only mode.3. Write mode updates only mismatched records.4. Running repair twice is idempotent.5. Scoped repair does not touch unrelated records.6. Recalculation uses canonical data only.7. Concurrent changes are not overwritten by stale expected state.8. Large repairs can run in batches.9. Repair output reports checked, mismatched, and changed counts.10. A rebuild can recover from a deliberately corrupted derived value.Recoverability of Derived Data Is an Architectural Property
A counter, projection, or index is safer when the system knows how to verify it against canonical data.
Then an incident does not begin by writing a one-off script. A tested path already exists: calculate expected state, report the difference, limit the scope, and perform an idempotent repair.
If data can be rebuilt, the ability to rebuild it should be designed together with the derived data itself.
Design derived-data repair while the system is healthy, not when production data already needs rescuing.